Claims With Receipts: How the Pressure Test Turns a Narrative Into a List of Proof and a Named Failure Mode
A diligence memo that says the story is unsupported gives you nothing to ask management; this post shows how the Pressure Test converts each narrative claim into the proof required, a curated precedent and a failure consequence, and where that precedent line stops being evidence.
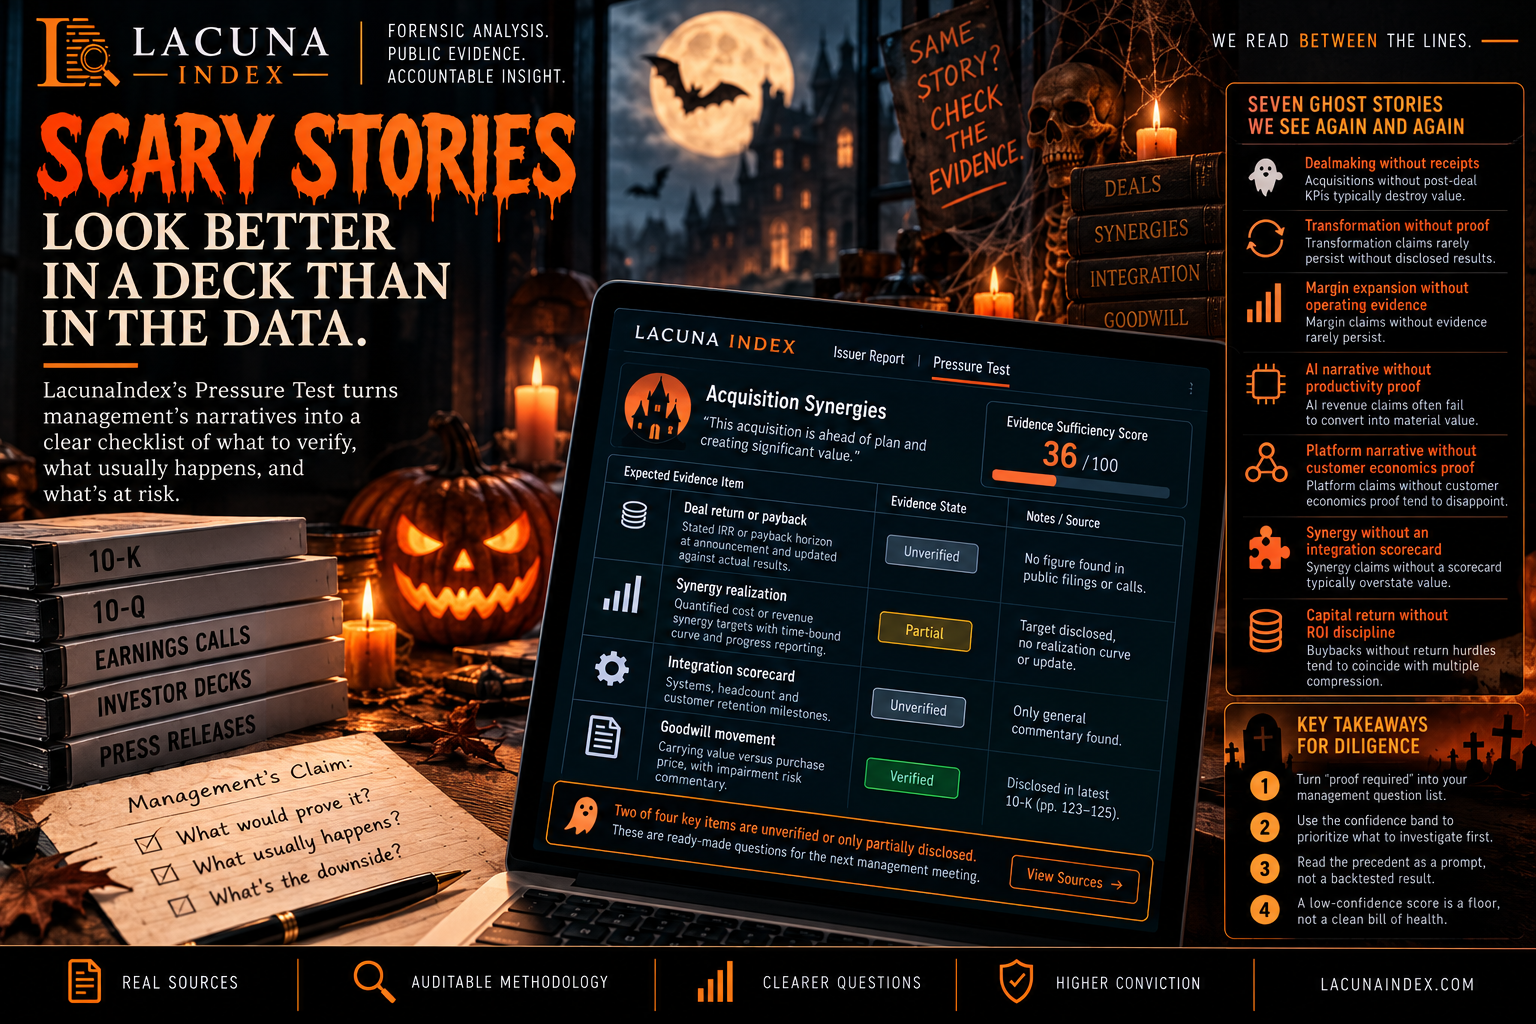
Most diligence memos contain a sentence like "management's transformation story is not yet supported by the numbers." It is probably true. It is also hard to act on, because it does not say what would change the conclusion. LacunaIndex's Pressure Test section is built to fix that. It turns each narrative claim into four things: the assumption the market is making, the proof that would justify it, the pattern that has followed similar claims before, and what happens if the proof never arrives.
This post explains how that section is assembled, what its "historical precedent" line is and is not, and how an analyst can use it.
The structure: five fields per item
Each item in the Pressure Test (the report calls them pressure items) has five fields:
- Market assumption. What the market must believe for the claim to hold. For the headline item this is the company's own strategic statement, taken from its stated vision, or failing that its one-line summary, or failing that its most repeated unfulfilled promise.
- Proof required. The specific disclosures that would substantiate it.
- Historical precedent. One sentence describing how this kind of claim has tended to play out.
- Failure consequence. What repricing or reset follows if the proof does not come.
- Confidence. A low, medium or high band, inherited from the confidence on the underlying gap or execution score. Our earlier post on score confidence covers what drives that band.
The report schema requires this structure, and the report also keeps a flat list of pressure points for older renderings. The report assembles up to four items per issuer. Each is anchored to a specific trigger, not generated from free text.
Where the items come from
The assembler works from data already in the report. It does not call a language model. The code states that every field is derived from the report payload and the evidence check, so the output is stable across reruns. That matters in diligence: if you re-run a report and the pressure items change, you cannot tell whether the company changed or the tool did.
Three anchors can produce an item:
- The headline narrative claim. This is always tested when a claim exists. Its proof list is the first three items from the issuer's expected-evidence checklist that are still missing (the checklist approach is described in our earlier post on expected evidence). Only if nothing is missing does it fall back to a default proof list for the matched pattern.
- Capital deployed into flagged investments. If any named investment is assessed as dragging on returns or as value-destructive, the assembler adds an item asking whether that capital is creating shareholder value.
- Ambition that outruns the operating base. If the report's calibration of ambition against return on investment reads "over-ambitious" or "fantasy," the assembler adds an item testing whether the forward ambition is supported by the current operating base.
If none of the three triggers fires, there are no items. The section does not invent pressure to fill space.
The precedent library
The "historical precedent" line is selected from a small, curated library of seven named patterns. They are:
- Dealmaking without receipts
- Transformation without proof
- Margin expansion without operating evidence
- Artificial intelligence narrative without productivity proof
- Platform narrative without customer economics proof
- Synergy without an integration scorecard
- Capital return without return-on-invested-capital discipline
Each pattern carries one sentence of precedent, a default list of proof to ask for, and a default failure consequence. For example, the synergy pattern asks for a dated integration scorecard with cumulative realisation, headcount, facilities and procurement contributions reported separately, and disclosure of revenue or customer losses caused by the integration. The capital return pattern asks for return on invested capital by segment, buybacks measured against an explicit return hurdle, and a return-of-capital framework tied to free cash flow conversion.
For the headline claim, the pattern is chosen by cue words in the claim and the gap signal (the investment item always uses the dealmaking pattern, and the ambition item always uses the margin pattern), checked from most specific to least. Artificial intelligence language is checked first, then platform language, then synergy or integration, then acquisitions, then margin or productivity, then buybacks. If nothing matches, the pattern defaults to "transformation without proof." The pattern identifiers are never renamed, because older reports may have stored them.
What the precedent line is, and what it is not
This is the part to be precise about. The precedent sentences are curated institutional language. They are written in the form "acquisitive issuers that don't publish post-deal KPIs typically destroy value" and "buyback programmes without disclosed return hurdles tend to coincide with multiple compression." They are not the output of a backtest, and the report does not attach a sample size or a hit rate to them. Selection is keyword matching, not a judgment about the company.
So treat the line as a prompt for your own challenge, not as evidence. The parts that are specific to the company are the claim, the missing-evidence list and the confidence band. The precedent supplies the vocabulary and the consequence to consider. If your firm has its own case history on a pattern, that should outrank our one-line summary.
Using it in a diligence workflow
A few practical uses:
Build the management question list from "proof required." Each item arrives as a list of concrete disclosures. Turn each into a request: "Provide the post-deal segment profit and loss against the pre-deal baseline for the last three acquisitions." That is a more productive request than "tell us about integration."
Separate absent from unpublished. The Pressure Test lists the evidence the company has not disclosed, up to six items. Missing from public disclosure does not mean the company lacks the data. It tells you what to ask for in a data room, and what you will have to estimate if you do not get it.
Use the consequence line to size the downside. If the claim is a platform story and the consequence is a single-product multiple, you can frame the valuation range as platform multiple versus single-product multiple and ask which the proof supports.
Check the keyword match. Because the headline pattern is chosen by cue words, a claim that mentions artificial intelligence in passing will be routed to the artificial intelligence pattern even if the real issue is margins. Read the matched pattern against the claim, and override it in your notes where it is wrong.
The limits
Up to four items per issuer is a deliberate cap, so the section is a short list of the main challenges and not a full risk register. The library has seven patterns, so some claims will fit imperfectly. The headline claim is only as specific as the company's own language. When a company has no testable claim at all, the report says so directly: it states that the issuer has not articulated a single, testable strategic claim. We think that is itself a finding.
The aim is simple. A narrative claim should come with a list of what would prove it, and a note of what usually happens when that list stays empty.